Detecting the rising edge of a short pulse

A reader is going through my ZedBoard tutorial and had some questions about detecting the rising edge of a pulse. The tutorial in question is using a ZedBoard to make a stopwatch. Kind of overkill in terms of hardware, but you have to start somewhere when you’re learning to code.

TRAN MINHHAI’s question asked: what do you do when the rising edge might just be a pulse, and the pulse might last less than a single clock cycle? The answer is to use a flip-flop with the input signal going to an asynchronous set input. The data input is just zero, and the clock signal is the one we are synchronizing to.

Here is the code:


`timescale 1ns/1ns
module edge_detect
  (
   input clk,
   input btnl,
   output btnl_rise
   );

  reg btnl_held = 0;
  always @(posedge clk or posedge btnl)
    if (btnl)
      btnl_held <= 1;
    else
      btnl_held <= 0;

  reg [1:0] btnl_shift = 0;
  always @(posedge clk)
    btnl_shift <= {btnl_shift,btnl_held};
  
  assign btnl_rise = btnl_shift == 2'b01;
endmodule

I also wrote a little test to go with it. Notice how short little pulses can come anywhere with respect to the clock edge:


`timescale 1ns/1ns
module edge_detect_test;

  reg clk = 0;
  always #10 clk = ~clk;

  reg btnl = 0;

  wire btnl_rise;

  edge_detect edge_detect(clk,btnl,btnl_rise);

  initial
    begin
      $dumpvars(0);
      
      @(posedge clk)
	btnl <= 1;
      repeat (10) @(posedge clk);
      btnl <= 0;
      repeat (4) @(posedge clk);
      #10 btnl <= 1;
      #1 btnl <= 0;
      repeat (4) @(posedge clk);
      #19 btnl <= 1;
      #1 btnl <= 0;
      repeat (4) @(posedge clk);
      #20 btnl <= 1;
      #1 btnl <= 0;
      repeat (4) @(posedge clk);
      $finish;
    end
endmodule

The long pulse case

In the case of a long pulse, the design works just like it would without the asynchronous set flip-flop. Here’s a timing diagram:

The short pulse case

But if there is a short pulse, the asynchronous set flip-flop holds the input value until there is a clock edge.

If the pulse appears in the middle of the clock cycle, then the timing diagram looks like this:

If the pulse appears right before the clock edge, then the timing diagram looks like this:

Now you know how to synchronize the rising edge of a pulse even if you have a slow clock.

Computing the Logarithm Base 2

Algorithm

Computing the log base 2 of a whole number is easy: just use a priority encoder. But what about a fixed point number? That sounds a lot harder. But, like many things, there’s a trick to make things easier.

Consider the following equation:

\log_2{x} = \log_2 (2^n \cdot 2^{-n} \cdot x) = n + \log_2(2^{-n} \cdot x)

If we choose n such that 2^{-n}\cdot x\in [1,2) , then n is just the whole number portion of the log. and we can compute that with a priority encoder. Furthermore, we can compute the 2^{-n}\cdot x portion by barrel-shifting the original number. Finally, we can use a lookup table to compute the lower bits. The nice thing about this is that the lookup table can be much smaller, since we only need to store the values between 1 and 2.

Another way to think about this is that the logarithm curve from [2,4) is the same as the one from [1,2), just shifted up by 2 and scaled horizontally by 2. Likewise the curve from [4,8) is scaled the same way. The algorithm is just taking advantage of this symmetry.

Oh– additionally, this algorithm only works on input values greater or equal to one, so the input and output values are always positive.

Implementation

Now, let’s code up our Verilog module. We’ll start with the module declaration:

module log2
 #(
 parameter in_int = 16,
 parameter in_frac = 8,
 parameter out_int = $clog2(in_int),
 parameter out_frac = in_int+in_frac-out_int,
 parameter lut_precision = 6,
 parameter register_output_stage = 0
 )

Since the module is dealing with a fixed-point input and output value, we need to specify how many integer and fractional bits there are in the input and output values. The lut_precision parameter specifies the log base 2 of the number of entries in our lookup table, and the default setting will be 64 entries in the table. There is also a parameter which allows for an optional final output register stage.

Next come the module ports:

  (
   input clk,
   input [in_int+in_frac-1:0] din,
   input din_valid,             // data in is valid
   output din_ready,            // ready to receive data
   output reg [out_int+out_frac-1:0] dout,
   output reg dout_valid,       // data out is ready (valid)
   output reg dout_error        // data out is incorrect - input data was less than 1.0
   );

We have the clock clk and the input value din. A handshake input indicating that the din value is valid. There is an output signal din_ready indicating that the module is ready to accept an input value. There is, of course, the output value dout, and a valid signal dout_valid. Since it is possible to provide an illegal input between 0 and 1, there is also a dout_error signal indicating the output value is not valid due to an inadmissible input value.
Now, let’s look at the body of the module:

  assign din_ready = 1;

Ready? Please. We’re always ready.

Pipeline Stage 1

Next, we instantiate the recursive priority encoder from my previous blog post. This takes the integer portion of the input value and produces the integer portion of the output value. There is also a prienc_error output which indicates that none of the input bits were set. This means we were given an input value that was less than one.

  wire [$clog2(in_int)-1:0] prienc_out;
  wire prienc_error;
  
  priencr #(in_int)
  priencr
    (
     .decode(din[in_frac+:in_int]),
     .encode(prienc_out),
     .valid(prienc_error)
     );

Next, we have the stage one pipeline logic:

  reg [$clog2(in_int)-1:0] stage1_prienc_out;
  reg stage1_error;
  reg stage1_valid;
  reg [in_int+in_frac-1:0] stage1_din;
  
  always @(posedge clk)
    begin
      stage1_din <= din;
      stage1_prienc_out <= prienc_out;
      stage1_error <= prienc_error;
      stage1_valid <= din_valid;
    end

Pipeline Stage 2

Stage two of the pipeline is the barrel shift logic. This shifts the input value to the left, based on the priority encoder output. Things are flipped, though, so lower priority encoder output values cause a larger shift. We’ll also pipeline the other signals:

  reg [in_int+in_frac-1:0] stage2_barrel_out;
  reg [out_int-1:0] stage2_barrel_out_int;
  reg stage2_error;
  reg stage2_valid;
  always @(posedge clk)
    begin
      stage2_barrel_out <= stage1_din << (in_int-stage1_prienc_out-1);
      stage2_barrel_out_int <= stage1_prienc_out;
      stage2_error <= stage1_error;
      stage2_valid <= stage1_valid;
    end

Pipeline Stage 3

The third pipeline stage is the lookup table, which computes the fractional part of the output. We will use an initial block to fill the table. First, we define a function to take the floating point log base-2 of an input value, since Verilog does not have one built in. Remember this rule from high school algebra?

  function real rlog2;
    input real x;
    begin
      rlog2 = $ln(x)/$ln(2);
    end
  endfunction

Next we declare the table and fill it in an initial block:

  reg [out_frac-1:0] lut[(1<<lut_precision)-1:0];
  integer i;
  initial
    begin : init_lut
      lut[0] = 0;
      for (i=1; i<1<<lut_precision; i=i+1)
        lut[i] = $rtoi(rlog2(1.0+$itor(i)/$itor(1<<lut_precision))*$itor(1<<out_frac)+0.5);
    end

Now, we need to use the barrel shift output as an address to the lookup table. We also carry along some of the stage 2 results:

  reg [out_frac-1:0] stage3_lut_out;
  reg [out_int-1:0] stage3_out_int;
  reg stage3_error;
  reg stage3_valid;
  always @(posedge clk)
    begin
      stage3_out_int <= stage2_barrel_out_int;
      stage3_lut_out <= lut[stage2_barrel_out[in_int+in_frac-2-:lut_precision]];
      stage3_error <= stage2_error;
      stage3_valid <= stage2_valid;
    end

Finally we have the code for the optional stage 4 pipeline. This is controlled by the register_output_stage parameter:

  generate
    if (register_output_stage)
      begin
        always @(posedge clk) dout = {stage3_out_int,stage3_lut_out};
        always @(posedge clk) dout_error = stage3_error;
        always @(posedge clk) dout_valid = stage3_valid;
      end
    else
      begin
        always @(*) dout = {stage3_out_int,stage3_lut_out};
        always @(*) dout_error = stage3_error;
        always @(*) dout_valid = stage3_valid;
      end
    endgenerate

Caveats

So there you have it: a module that computes log base 2 for fixed point inputs. However, there ‘s still one tiny problem: the design is not synthesizable by XST or Vivado. I haven’t tried other tools, but they may have issues with it as well.

The issue is that the tools don’t seem to implement the built-in Verilog floating point functions during elaboration. Essentially, the synthesis tool needs to run the initial block in order to know how to populate the lookup table. In general, the tools can do this. However, if they catch wind of a float value, they tuck their tail between their legs and run.

My workaround for this is to use the Perl preprocessor I describe in a previous blog post. But that’s a topic for another time.
Remote debugging with the Arrow SoCkit board

Background

My FPGA builds are done on a server in the datacenter, which is helpful for a number of reasons, not the least of which is that it takes a lot of CPU, and the server has plenty of CPU power. However, it’s a pain to transfer the design files over to a local machine for programming and debugging. Here are instructions that you can use to run just a JTAG server on the lab machine, and connect to from the server machine.

Lab Machine

Install

You should install the Quartus II tools on the lab machine. There’s got to be a download for only the programming tools, but I haven’t found it yet. Download and install only the minimal amount. The machine needs to run the port mapper and xinetd. You may need to install those with yum or whatever other package manager your distribution requires.

Starting the Server

In the following, I assume that the environment variable $qII points to your Quartus II install directory.

You need to make sure that a file /etc/jtagd/jtagd.conf exists and has the following line in it:

Password = “mysecret”

Without that, the jtag daemon will not listen for remote machines.

First check that the JTAG software can see the board. Run the following command and verify that you get the correct output…

[pete@localhost ~]$ $qII/quartus/bin/jtagconfig
 1) CV SoCKit [1-1]
 02D020DD 5CSEBA6(.|ES)/5CSEMA6/..
 4BA00477 SOCVHPS

Then, run the following to start the server. You need to do this as root:

[pete@localhost ~]$ sudo $qII/quartus/bin/jtagd
[pete@localhost ~]$ sudo $qII/quartus/bin/jtagconfig --enableremote mysecret

Remote Machine

On your remote machine you should start up Quartus II, and:

Select Tools->Programmer. This will start the programmer window.
You should then click the Hardware Setup… button.
Click on the JTAG Settings tab.
Click the Add Server… button.
Enter the IP address of your server. Enter the password, greywolf.
The Hardware Setup window should indicate the server IP address and the connection status should be OK.
Click the Close button.
You should then see the IP address of the lab machine to the right of the Hardware Setup… button.

You should now be able to use the JTAG device from the remote machine.

Pro Tips

If your lab machine doesn’t have a public IP address– for instance, because it is a VM using NAT running on a host with a VPN connection to your server– you will need to set up an SSH tunnel to the lab machine.

The JTAG server runs on port 1309. You can use ssh to tunnel the connection.

From your VPN machine ssh to the remote machine with the following command:

[pete@localhost ~]$ ssh -L 1309:192.168.1.2:1309 user@myserver.mydomain.com

In this example, your guest machine has an IP address of 192.168.1.2, and the remote server is myserver.mydomain.com.

Then, you would use your VPN machine IP address as the address of the lab machine when connecting to the JTAG server.


Timing Diagrams with WordPress

I saw a post yesterday on Hackaday about using a program called Wavedrom to edit timing diagrams on web pages. It looks like a great tool, but I have a couple of issues with it.

First, I’m confused about the command line version of the tool. It exists, but there seems to be some issue with using it on Mac OS. I haven’t tried it on Linux yet, but most of my work is done on both, especially documentation, so I need to get that figured out.

The second really big gotcha is that it doesn’t work with Internet Explorer 9 and earlier. That is a big one. Even though I personally never use IE, a lot of my readers do.

Anyway, with those caveats in mind, I did some work to try to integrate Wavedrom with WordPress. Here is an example waveform:

Apologies if you use IE since you can’t see the waveform. You can check it out in Firefox or Chrome, though.

You can see the full tutorial for WaveDrom here for more details. But for the example above, the code embedded in this page looks like this:

<script type="WaveDrom">
{ signal : [
{ name: "clk", wave: "p......" },
{ name: "bus", wave: "x.34.5x", data: "head body tail" },
{ name: "wire", wave: "0.1..0." },
]}
</script>

I created a very simple plugin for WordPress which adds the right stuff to the HTML header for these pages. I will probably work on it a bit further if I can figure out how to support IE. If I can’t do that, maybe I can get the command line version working, and use it for PNG or SVG images at least.

Putting New Files in the Right Place: The Vivado Edition

Vivado has the ability to create and manage your own IP, which is a good thing. But there are some real gotchas when doing something like this, the first being that it doesn’t seem to place HDL files in the correct locations.

I have been running some FPGA workshops using the IP Packager in Vivado and having been having a lot of problems when creating new files in the IP component. Here’s an example:

From a Vivado project select Tools→Create and Package IP… Click Next, select Create a new AXI4 peripheral, click Next, just use the defaults for the next page, click Next again, use the defaults for the AXI information and click Next again, select Edit IP, then click Finish.

This will put in an IP Packager project. Edit the top level file myip_v1_0. I’m using Verilog but it works the same for VHDL. Instantiate a new dummy module at the bottom of the file:

// Add user logic here
dummy dummy (.clk(s00_axi_aclk));
// User logic ends

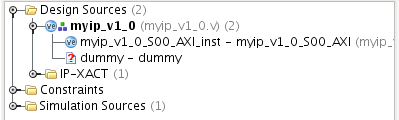
files_fig1Save the file and look at the design sources. You will see that there is now a new undefined module in the design called dummy. It should look like the figure to the right:

Now, we would like to create the new module. So we go to File→Add Sources… and create the new source file. Select Add or create design sources and click Next. Click Create File …, type the file name dummy and click OK. Click Finish. When the Define Module dialog pops up, just click OK. Click Yes to the dialog saying you haven’t changed anything. You now have a file defined for your dummy module.

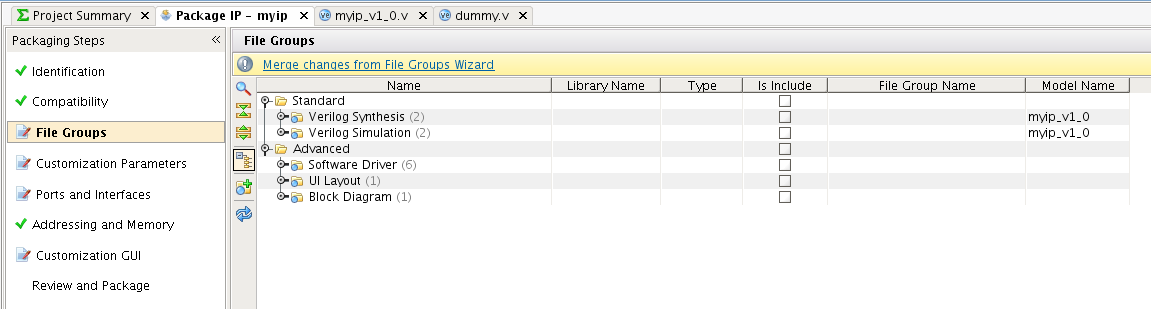
files_fig2Ready to package that IP? Go to the Package IP tab in the Project Manager window. Then, select File Groups in the Packaging Steps window. You should see a window like the figure on the right.

Now click on the Merge changes from File Groups Wizard link. You will then get a link saying 2 warnings. Click on that, and you will see two warnings about your dummy.v file being on a path which is not relative to your IP root directory. What has happened is that Vivado placed the new file outside the IP component. If you go ahead and package your IP, you cannot use the packaged IP because it will be missing this file. Seems like a Vivado (2014.4) bug to me.

So how should we fix this? I don’t know how to move files in Vivado, but we can create the file in a different location when we make the new file. To do that, first delete the dummy file and remove it from disk. Just select the file, then right-click and select Remove File from Project. Select the checkbox to also delete it from disk and click OK.

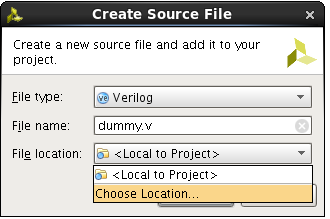
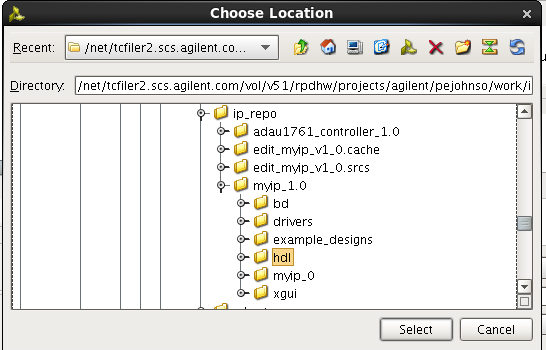
files_fig3Now go to Add Sources again, and after clicking Create File…, specify the file name dummy.v, then select a new file location. files_fig4Navigate to your ip_repo area and into myip_1_0. Select the hdl directory, and click Select. Then click OK and then Finish to create the file. This will place the file in the proper location in the IP repository.

When you merge your changes in the File Groups step, you should not get any warnings. You can then package your IP and use it in your designs.

Hopefully this will be fixed in the next release of Vivado.

Getting Xilinx Document Navigator working with CentOS 6.5

There are a number of packages you need to install beyond the default to get Document Navigator working on CentOS 6.5. What’s especially strange is that they are 32-bit libraries, which are required even on 64-bit machines. Here is the yum command I used to get everything to work. We’ll have a couple of frustrations, because the latest CentOS 6 repositories are for CentOS 6.6, which is not compatible with the latest Vivado release. So you’ll also need to update a few things on the x86_64 side before doing the install for the i686 libraries:


% sudo yum update libXrender glib2
% sudo yum install fontconfig.i686 libXext.i686 libXrender.i686 glib2.i686 libpng.i686 libSM.i686

Why is Xilinx 2014.4 SDK so buggy on Linux?

I am running CentOS 6.6 with Vivado and SDK, but SDK has been crashing like crazy on me. It dies with the following message.

java: cairo-misc.c:380: _cairo_operator_bounded_by_source: Assertion `NOT_REACHED' failed.

Turns out it is a problem with versioning between gtk2 and cairo. Here is a link with the details.

There are some posts on the Xilinx forum about installing updated RPMs to fix this, but it is not a good idea to install RPMs outside of the YUM framework. Another alternative is to disable cairo in eclipse. So edit your eclipse configuration file in install_dir/SDK/2014.4/eclipse/lnx64.o/configuration/config.ini (and the 32-bit version if that is appropriate) to include the following line.

org.eclipse.swt.internal.gtk.cairoGraphics=false

This seems to have fixed things at least for now.

Remote JTAG with Vivado

My FPGA development computer is a server in a datacenter. It stores lots of memory and CPU, but it’s impossible to connect it directly to my development boards. ISE has always supported remote JTAG servers, but the implementation has always been spotty. In some releases it has difficulty with some versions of Linux. With Vivado, things are much improved.

If your lab machine is on the same network as your development machine, simply start the hw_server program in the Vivado bin directory and open a target from the development machine Vivado window. Just specify a remote server host name and use the default port 3121. It couldn’t be simpler.

If your lab machine is behind a firewall, you may need to use SSH to tunnel the traffic through. First, make sure the hardware manager is not running on your development machine. From the lab machine, ssh into the development machine with the following command:

ssh -R 3121:localhost:3121 development.my.com

This will create an SSH tunnel from your lab machine to your development machine. If you get a warning saying that SSH can’t bind to the required port it means you are still running a local JTAG server on your development machine. Assuming all went well you should be logged in to your development machine from the lab machine. You can then open the target in the hardware manager in Vivado but tell it to connect to a local machine. Vivido will see a server already running on port 3121 (through your SSH tunnel), so it won’t try to start a new one.

If your lab machine is running Windows then you can use the open source PuTTY program to make the tunnel. If your development machine is running Windows, then you need to install an SSH server on the machine. That’s beyond the scope of this post.

Dual LIFO

The lifo2 module implements a dual Last In First Out stack data structure. The two stack structures share a single block RAM, or may optionally be constructed from shift registers. This module forms the heart of a stack based micro-controller. One of the stacks is used as a data stack while the other is used as a subroutine call stack. By implementing these in a single BRAM we can save a lot of space.

1. Interface

The module interface consists of a clock and reset signal, and a control interface for each stack.

1.1. Module declaration

§1.1.1: §7.1

module lifo2
  §1.3.1. Parameters
  (
   input clk,
   input reset,
   §1.2.1.1. Stack port A,
   §1.2.2.1. Stack port B
   );
      

1.2. Stack ports

The two ports use the suffix a and b to distinguish interface signals. A push input indicates that data from the push_data input should be pushed onto the stack. A pop input indicates that data should be popped from the stack. Popped data should be read from the tos output during the same cycle that pop is valid. It is completely normal to push and pop data on the same clock cycle.

Status signals empty and full indicate if the stack is empty or full. The count output provides the number of valid entries currently on the stack.

1.2.1. Stack port A

§1.2.1.1: §1.1.1

   input push_a,
   input pop_a,
   output reg empty_a,
   output reg full_a,
   output reg `CNT_T count_a,
   output `DATA_T tos_a,
   input `DATA_T push_data_a
	

1.2.2. Stack port B

§1.2.2.1: §1.1.1

   input push_b,
   input pop_b,
   output reg empty_b,
   output reg full_b,
   output reg `CNT_T count_b,
   output `DATA_T tos_b,
   input `DATA_T push_data_b
	

1.3. Parameters

A depth parameter specifies the depth for each of the stacks. For the BRAM implementation, the size of the RAM is just the sum of the two depth parameters. For the shift register implementation each stack uses its depth parameter independently. The width parameter specifies the data width. This is the same for both stacks.

The implementation parameter may be set to "BRAM" or "SRL" to select between BRAM and shift register implementations. Note that the quotes are required.

The full_checking specifies whether the logic that generates the full outputs should be generated. In the case of the shift register implementation the concept of full is easy to implement and sensible. With this implementation, there really are two independent stacks. However, with the BRAM implementation the concept of full is a little harder to pin down. Is the stack full when the number of elements is equal to its depth parameter? This seems overly restrictive since there may still be plenty of room for it to grow. But if it does grow then it does so at the expense of the other stack. There is a further difficulty if both stacks are almost full. If you push to both stacks then you will overflow one of the stacks. Which one? The one that is already over its posted limit? The logic to implement this seems needlessly complex. So the compromise here is to implement the strict full checking for the BRAM implementation when the full_checking parameter is true and to not generate any full checking logic at all if it is false.

§1.3.1: §1.1.1

  #(
    parameter depth_a = 512,
    parameter depth_b = 512,
    parameter width = 32,
    parameter implementation = "SRL",
    parameter full_checking = 0,
    parameter depth = depth_a+depth_b
    )
      

1.4. Definitions

Here are some definitions that we can make use of later. DATA_T is used for data values. PTR_T is used for pointers like the top of stack pointer. The CNT_T definition is suitable for holding a count. Note that this value needs to hold a value of 0 as well as a value of depth so it may be larger than the PTR_T value.

§1.4.1: §7.1

`define DATA_T [width-1:0]
`define PTR_T [log2(depth)-1:0]
`define CNT_T [log2(depth+1)-1:0]
      

2. Functions

The log2 function computes the log base 2 of its input value. This function is used to computer widths of pointer and count values.

§2.1: §7.1

   function integer log2;
      input [31:0] value;
      begin
	 value = value-1;
	 for (log2=0; value>0; log2=log2+1)
	   value = value>>1;
      end
   endfunction
    

3. Logic common to all implementations

3.1. Determine read and write signals

The writing signals indicate that we are writing to the corresponding stack. This occurs when the push signal is asserted and there is space on the stack or if the push signal is asserted and a pop is asserted as well. In this case we can perform the operation even though the stack is full.

The reading signal indicates that we are reading from the corresponding stack. It is just the pop signal qualified with not empty.

§3.1.1: §7.1

  wire writing_a = push_a && (!full_a || pop_a);
  wire writing_b = push_b && (!full_b || pop_b);
  wire reading_a = pop_a && !empty_a;
  wire reading_b = pop_b && ! empty_b;
      

3.2. Determine count value for stack A

We first generate the next_count_a value. Incrementing if we are writing but not reading, decrementing if we are reading and not writing and leaving the count the same if we are both reading and writing or neither reading or writing. We use a separate combinational always block to generate a next value signal next_count_a. This signal is used by later code to determine empty and full conditions.

§3.2.1: §7.1

  reg `CNT_T next_count_a;
  always @(*)
    if (writing_a && !reading_a)
      next_count_a = count_a + 1;
    else if (reading_a && !writing_a)
      next_count_a = count_a - 1;
    else
      next_count_a = count_a;

  always @(posedge clk)
    if (reset)
      count_a <= 0;
    else
      count_a <= next_count_a;
      

3.3. Determine count value for stack B

Here we generate the count values for stack B.

§3.3.1: §7.1

  reg `CNT_T next_count_b;
  always @(*)
    if (writing_b && !reading_b)
      next_count_b = count_b + 1;
    else if (reading_b && !writing_b)
      next_count_b = count_b - 1;
    else
      next_count_b = count_b;
  
  always @(posedge clk)
    if (reset)
      count_a <= 0;
    else
      count_b <= next_count_b;
      

3.4. Generate empty

Here we generate the logic for determining if either stack is empty. The stack is empty if on the next clock its count will be zero.

§3.4.1: §7.1

  always @(posedge clk)
    if (reset)
      empty_a <= 1;
    else
      empty_a <= next_count_a == 0;

  always @(posedge clk)
    if (reset)
      empty_b <= 1;
    else
      empty_b <= next_count_b == 0;
      

3.5. Generate full

Full is pretty simple as well. We go full when the next count value will be equal to the depth parameter of the stack. Writes will not occur when the stack is full so there can never be a case when the next count value is greater than the depth.

§3.5.1: §3.6.1

  always @(posedge clk)
    if (reset)
      full_a <= 0;
    else
      full_a <= next_count_a == depth_a;

  always @(posedge clk)
    if (reset)
      full_b <= 0;
    else
      full_b <= next_count_b == depth_b;
      

3.6. Conditionally generate the full logic

As discussed in Section 1.3, “Parameters”, based on the value of the full_checking parameter we either create the checking logic or just stub the full signals out to always false.

§3.6.1: §7.1

  generate
    if (full_checking)
      begin
        §3.5.1. Generate full
      end
    else
      begin
	initial full_a = 0;
	initial full_b = 0;
      end
  endgenerate
      

4. BRAM implementation

This section describes the BRAM implementation of the dual LIFO.

4.1. The data memory

§4.1.1: §4.6.1

  reg `DATA_T mem [depth-1:0];
      

4.2. Maintain address pointers

Figure 1. The pointer to the top of the A stack grows down while the pointer to the top of the B stack grows up


Here we maintain the address pointers into the RAM. The pointer for stack A starts at address zero and works up, while the pointer for stack B starts at the last address and works down.

§4.2.1: §4.6.1

  wire `PTR_T ptr_a = writing_a ? count_a `PTR_T : (count_a `PTR_T)-1;
  wire `PTR_T ptr_b = (depth-1)-(writing_b ? count_b `PTR_T
                                           : (count_b `PTR_T)-1);
      

4.3. Top-of-stack

One limitation of the BRAM implementation is that we only have two ports. One port must be used for each stack since both stacks can operate simultaneously. The solution to this problem is to recognize that if we are both pushing and popping the stack then we are really only operating on the top element. This element can be stored in a register and no actual memory operation needs to occur.

4.3.1. Top-of-stack shadow registers

The tos_shadow registers hold the latest value pushed onto the stack.

§4.3.1.1: §4.6.1

  reg `DATA_T tos_shadow_a;
  always @(posedge clk)
    if (reset)
      tos_shadow_a <= 0;
    else if (writing_a)
      tos_shadow_a <= push_data_a;

  reg `DATA_T tos_shadow_b;
  always @(posedge clk)
    if (reset)
      tos_shadow_b <= 0;
    else if (writing_b)
      tos_shadow_b <= push_data_b;
	

4.3.2. Select between top-of-stack shadow registers and memory read values

Here we determine if we should use the memory read value or the top-of-stack shadow register to provide the top-of-stack value. If we are popping the stack then the new top-of-stack value should come from the memory read. Otherwise we should just use the value in the top-of-stack shadow register.

§4.3.2.1: §4.6.1

  reg use_mem_rd_a;
  always @(posedge clk)
    if (reset)
      use_mem_rd_a <= 0;
    else if (writing_a)
      use_mem_rd_a <= 0;
    else if (reading_a)
      use_mem_rd_a <= 1;

  reg use_mem_rd_b;
  always @(posedge clk)
    if (reset)
      use_mem_rd_b <= 0;
    else if (writing_b)
      use_mem_rd_b <= 0;
    else if (reading_b)
      use_mem_rd_b <= 1;

  assign tos_a = use_mem_rd_a ? mem_rd_a : tos_shadow_a;

  assign tos_b = use_mem_rd_b ? mem_rd_b : tos_shadow_b;
	

4.4. Perform memory reads

Here we read from the stack. The values read will be the top-of-stack outputs if we are reading from the stack but not writing to it.

§4.4.1: §4.6.1

  reg `DATA_T mem_rd_a;
  always @(posedge clk)
    if (reading_a)
      mem_rd_a <= mem[ptr_a];

  reg `DATA_T mem_rd_b;
  always @(posedge clk)
    if (reading_b)
      mem_rd_b <= mem[ptr_b];
      

4.5. Perform memory writes

Conversely if we are writing to the stack but not reading then we perform a memory write.

§4.5.1: §4.6.1

  always @(posedge clk)
    if (writing_a && !reading_a)
      mem[ptr_a] <= tos_a;

  always @(posedge clk)
    if (writing_b && !reading_b)
      mem[ptr_b] <= tos_b;
      

5. Shift register implementation

5.1. Shift register implementation of stack A

There may be situations where two stacks are needed but we don't want to use a block RAM, or if both stacks don't need to be very large and we want to save the overhead of the RAM implementation. This alternate shift register implementation may be used instead.

The basic idea of the shift register implementation is to use a shift register for each bit of the data word. We then concatenate the head of the shift registers together to form the top of the stack.

5.1.1. Pop data off the shift register

Here we shift the register left, shifting in a zero value.

§5.1.1.1: §5.1.1

srl <= {srl[depth-2:0],1'b0}
	

5.1.2. Push data onto the shift register

Here we shift the push data onto the shift register. This will only happen when the shift register is not full.

§5.1.2.1: §5.1.1

srl <= {push_data_a[i],srl[depth_a-1:1]}
	

5.1.3. Swap data at the top of the shift register

Here we just replace the leftmost value in the shift register with the new pushed value.

§5.1.3.1: §5.1.1

srl <= {push_data_a[i],srl[depth_a-2:0]}
	

We use a generate for loop to implement each shift register and a case statement to update it based on the push and pop conditions.

§5.1.1: §5.1

for (i=0; i<width; i=i+1)
  begin : srl_a
    reg [depth_a-1:0] srl;
    always @(posedge clk)
      case ({writing_a,reading_a})
	2'b01: §5.1.1.1. Pop data off the shift register;
	2'b10: §5.1.2.1. Push data onto the shift register;
	2'b11: §5.1.3.1. Swap data at the top of the shift register;
      endcase

      assign tos_a[i] = srl[depth_a-1];
  end
      

5.2. Shift register implementation of stack B

The implementation for stack B is the same as for stack A but with the appropriate name changes.

§5.2.1: §5.1

for (i=0; i<width; i=i+1)
  begin : srl_b
    reg [depth_b-1:0] srl;
    always @(posedge clk)
      case ({writing_b,reading_b})
	2'b01: srl <= {srl[depth_b-2:0],1'b0};
	2'b10: srl <= {push_data_b[i],srl[depth_b-1:1]};
	2'b11: srl <= {push_data_b[i],srl[depth_b-2:0]};
      endcase
      assign tos_b[i] = srl[depth_b-1];
  end
      

For the shift register implementation we just declare the generate loop variable and then instantiate the two stacks.

6. Undefined implementation

§6.1: §7.1

	initial
	  begin
	    $display("***ERROR: %m: Undefined implementation \"%0s\".",implementation);
	    $finish;
	  end
    

7. The main module

This is where we tie everything together.

§7.1

§1.1. Header
§2.1. Copyright

`timescale 1ns/1ns
§1.4.1. Definitions

§1.1.1. Module declaration

§2.1. Functions

§3.1.1. Determine read and write signals

§3.2.1. Determine count value for stack A
§3.3.1. Determine count value for stack B

§3.4.1. Generate empty
§3.6.1. Conditionally generate the full logic

`ifndef SYNTHESIS
   initial
     $display("***INFO: %m: lifo2.v implementation=\"%0s\".",implementation);
`endif
  generate
    if (implementation == "BRAM")
      begin : bram_implementation
        §4.6.1. BRAM implementation body
      end
    else if (implementation == "SRL")
      begin : srl_implementation
        §5.1. Shift register implementation
      end
    else
      begin
        §6.1. Undefined implementation
      end
  endgenerate
endmodule
    

A. Front matter

1. Header

§1.1: §7.1

//-----------------------------------------------------------------------------
// Title         : Dual LIFO stack
// Project       : Common
//-----------------------------------------------------------------------------
// File          : lifo2.v
//-----------------------------------------------------------------------------
// Description :
// 
// Two Synchronous LIFO stacks using a single BRAM.
//
// The stacks start at each end and grow to the middle.
//
      

2. Copyright

§2.1: §7.1

//-----------------------------------------------------------------------------
// Copyright 2009 Beyond Circuits. All rights reserved.
//
// Redistribution and use in source and binary forms, with or without modification,
// are permitted provided that the following conditions are met:
//   1. Redistributions of source code must retain the above copyright notice, 
//      this list of conditions and the following disclaimer.
//   2. Redistributions in binary form must reproduce the above copyright notice, 
//      this list of conditions and the following disclaimer in the documentation 
//      and/or other materials provided with the distribution.
//
// THIS SOFTWARE IS PROVIDED BY THE BEYOND CIRCUITS ``AS IS'' AND ANY EXPRESS OR 
// IMPLIED WARRANTIES, INCLUDING, BUT NOT LIMITED TO, THE IMPLIED WARRANTIES OF 
// MERCHANTABILITY AND FITNESS FOR A PARTICULAR PURPOSE ARE DISCLAIMED. IN NO EVENT 
// SHALL BEYOND CIRCUITS BE LIABLE FOR ANY DIRECT, INDIRECT, INCIDENTAL, SPECIAL,
// EXEMPLARY, OR CONSEQUENTIAL DAMAGES (INCLUDING, BUT NOT LIMITED TO, PROCUREMENT
// OF SUBSTITUTE GOODS OR SERVICES; LOSS OF USE, DATA, OR PROFITS; OR BUSINESS 
// INTERRUPTION) HOWEVER CAUSED AND ON ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, 
// STRICT LIABILITY, OR TORT (INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY 
// OUT OF THE USE OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
//------------------------------------------------------------------------------
      

B. Downloads

The Verilog code for lifo2.v can be downloaded here. Since this post is so long I have also included a link the article in PDF form here.

A Verilog Preprocessor

A long time ago…

When I used to work at Silicon Engineering in the nineties, I wrote a Verilog preprocessor using Perl. Verilog ’95 is pretty limited in what it can do, so we used this preprocessor on our projects to enhance our Verilog code. Back in the Verilog ’95 days, we used to write every RTL file as a preprocessor file and used GNU Make to convert it into pure Verilog. What with Verilog 2005 and System Verilog, these days I only use this preprocessor when necessary. But that’s still pretty often.

The trick

The cool thing about this preprocessor is that it does very little of the work on its own. It can be used in place of the standard Verilog preprocessor– which is well and good if you need that type of thing, but it’s still pretty limited. After all, you already have something that does that. This preprocessor’s neat trick is that you can embed Perl code inside your Verilog code. What the preprocessor does, essentially, is it converts the input code into a perl program which, when run, prints the input code. Now, by itself that is kind of boring. However the preprocessor allows you to use special comments to drop out of this mode and embed Perl code.

A simple example

One simple example of what you can do is to build a table to use in your Verilog module. In my CORDIC module, I needed a table of arctan values. This table is static and doesn’t ever need to change. All I needed was one entry in the table for each pipeline stage in the CORDIC. The table takes the pipeline stage number as input and returns a 64-bit value as the result. I implemented this as a function which is basically just a big case statement. You can see the special comment is wrapped in a /*@ and @*/ pair. I chose these because they are real Verilog comments so they won’t mess up editors that know how to edit Verilog (like Emacs). Once you drop into Perl mode, anything that your Perl code writes to standard output will appear in the preprocessor output. Here is the input to the preprocessor:

   function [63:0] k_table;
      input [5:0] index;
      begin
	 case(index)
/*@
  $k = 1;
  for my $i (0..63)
    {
      $k *= cos(atan2(1,2**$i));
      printf "%8d: k_table = 64'd%s; // %.20e\n",$i,int($k*2**64+.5),$k;
    }
 @*/
	   default: k_table = 0;
	 endcase
      end
   endfunction

Interpolation

Code enclosed within the /*@ and @*/ pairs, or prefixed with the //@ comment, is just copied into the output Perl program. Other lines are just printed by the Perl program, which means you can use Perl string interpolation on those lines. Here’s a rather contrived example:

//@ my $reset_style = " or negedge clk";
always @(posedge clk $reset_style)
  q <= d;

In this example, the Perl reset_style variable is used in the verilog code without needing to drop into the more cumbersome comment syntax. This can help make your code a lot more readable. I have a library that I commonly use which defines a bunch of variables. These variables match the Verilog system tasks and functions that begin with a dollar sign ($). This way, you can say $display and the preprocessor will expand the Perl variable display (which, by the way, conveniently has the value $display.)

Other Possibilities

I also write a lot of structured documentation for my designs using XML. By using the XML::LibXML library I can read the XML documentation from my Verilog code and parse that for information that drives the RTL code generation. So I can document registers, instruction sets, interrupts, or other types of information, and then that do generate my verily code.

Useful Links

Look for more posts using this technique soon.